Let me be honest. This project wasn't born from a desire to "do AI". It was born from frustration, and a very concrete one: my internship applications.
For every opening, I adapted my CV. But the AI helping me didn't know me, or was out of date. I had to re-explain my context, my experience, my projects, whatever matched the role. And I kept forgetting details. So I'd go fetch that context from another AI that had kept it, then bring it back to the first. My own profile was scattered across several AIs, each with its own version of me.
This article tells how I built a "second brain" to fix that. Step by step, with the struggles and the solutions. The final result matters less to me than the road to get there.
The architecture principles
Behind the tools, there's a chain of principles. It's what structures everything else.
Source of truth
      ↓
Projection
      ↓
Retrieval
      ↓
Controlled access
      ↓
Controlled write
      ↓
Verification
The vault is the source of truth. Everything else is just a projection of it. The AI never touches the source directly: it goes through controlled access, a controlled write, then human verification. That thread ties together everything that follows.
The starting point: re-explaining my life to a machine
The trigger was a simple question. Why do I keep wasting time re-explaining my context to tools that never forget theirs?
I wanted a memory that was:
- mine, not locked inside a tool that might shut down tomorrow;
- portable, readable by any AI, whichever it is;
- readable and writable, so the AI can use it but also add to it, under my control;
- private, so my notes don't go off to be indexed by a third party.
From there, the architecture almost imposed itself.
Building it, step by step
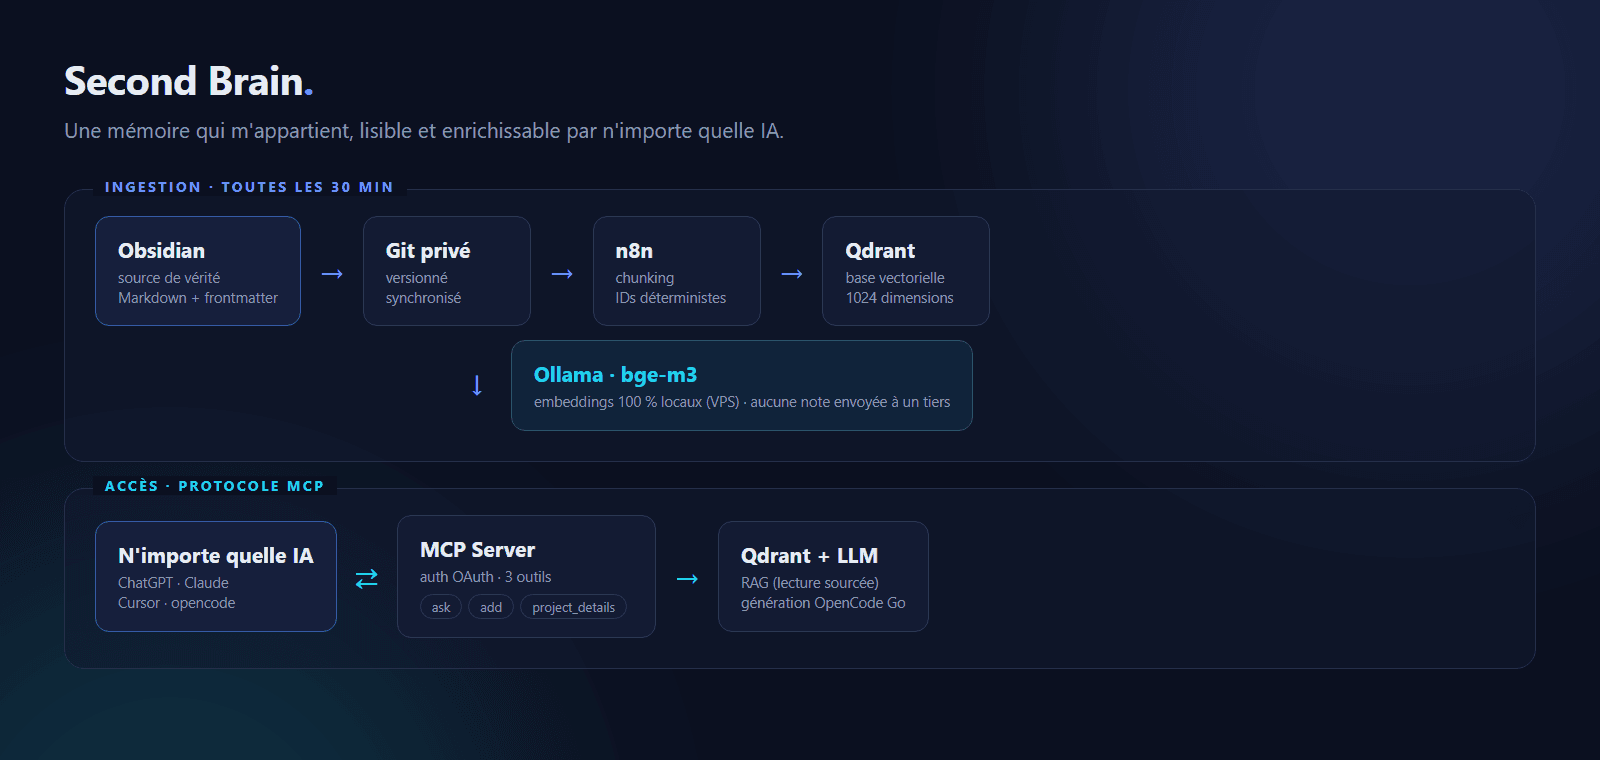
The big picture. The vault is the source of truth, ingestion projects it into Qdrant, and the MCP server opens it to any AI.
Step 1: the Obsidian vault as the source of truth
First choice: Obsidian. Markdown files, one topic per note, with YAML frontmatter (type, status, importance, tags). Why Markdown? Because it's plain text. Readable by a human, diffable, versionable, and it depends on no software. The vault lives on my disk and on a private GitHub repo, so full history and automatic sync.
That's the foundation. The vault is the single source of truth. Everything else is just a projection of it.
Markdown files, one topic per note, linked to each other.
Step 2: the ingestion pipeline
For an AI to read those notes, they must be turned into data searchable by meaning. That's the job of a RAG (Retrieval-Augmented Generation): split notes into pieces (chunks), compute a vector for each (a number that summarizes its meaning), and store them in a vector database.
My pipeline, orchestrated with n8n, which I already use everywhere:
GitHub (private vault) → decoding → chunking → embeddings → QdrantQdrant is the vector database. It's self-hosted on my VPS and open source. For embeddings, I use Ollama with the bge-m3 model: it runs locally, it's multilingual, and no note is ever sent to a third party.
Important: ingestion runs every 30 minutes. I write in Obsidian, push, and thirty minutes later it's queryable. No button to click.
The ingestion pipeline in n8n: reading the vault, chunking, filtering already-indexed chunks, embeddings, upsert and cleanup.
Step 3: the RAG, asking a question
A question comes in. It's turned into a vector. Qdrant finds the closest pieces. An LLM answers only from those pieces, citing the source files.
The vector map. Each point is a chunk, and the tooltip shows the direct link between a vector and its content.
The query pipeline in n8n: this is the workflow the second_brain_ask MCP tool calls.
Choosing the LLM was eventful (more on that in the problems section). Today, generation goes through the OpenCode Go gateway, with the model deepseek-v4-flash-vision-exp.
Step 4: the MCP server, plugging in any AI
This is the centerpiece, and what sets this project apart from a simple chatbot. The MCP protocol (Model Context Protocol) lets any compatible AI connect to my tools: ChatGPT, Claude, Cursor, opencode.
I built a dedicated MCP server that exposes only my tools, never n8n's admin surface. One URL is enough, and my brain is plugged into all my AIs:
https://n8n.samensteeve.com/mcp/second-brain-kbIn practice, in a Claude conversation, I can write "query my second brain: what are my Laravel projects?" and it searches my notes, with sources.
The key point isn't the RAG itself: a classic "Obsidian + chatbot" already does that. What changes everything is interoperability: the same base serves ChatGPT, Claude, Cursor and opencode, with no duplication. And the server exposes only my tools, never n8n's admin surface.
The MCP server exposes only my tools (read, quarantined write, source reading), never n8n's admin surface.
Step 5: controlled writing, quarantine
Giving an AI the ability to write into my base is powerful and dangerous. A note read by an AI, or a booby-trapped piece of content, could push it to write anything. My rule is simple: every AI write goes through quarantine.
A note proposed by an AI arrives with status: pending. It's invisible to search until I've validated it by hand. Within that frame, the worst a compromised AI can do is write a note I can see, that I can fix or delete. And everything is versioned by Git, so it's reversible.
Step 6: quality, classification, duplicates, housekeeping
A base that grows quickly becomes a mess. I put in three safeguards.
First, automatic classification. An AI proposing a note assigns it a type, tags and a target folder. Then deduplication: before writing, the note is compared to what already exists. Too similar (above 75%), it's refused. Slightly similar (above 55%), it's a warning. Finally, weekly housekeeping: a workflow detects redundant note pairs and writes me a report to review.
Step 7: diving into the source
A knowledge base is good. But sometimes the AI needs the exact detail: a specific file from a project, the real implementation of a feature.
Rather than copying everything into the vault, I added a third tool: second_brain_project_details. The AI asks for a repo (or repo#path), and it reads the source directly on GitHub.
In practice: "how did I implement escrow?", "I want to rebuild this feature elsewhere, show me how I did it". The AI goes to find the real implementation, in the real code. The vault stays light, the source stays the truth.
Today, that tool is wired to GitHub. But nothing stops it from being wired to other tools tomorrow: GitLab, an issue tracker, internal docs. That's the powerful part: the same base can open the AI to my whole work environment.
Step 8: authentication
The last brick to make it work everywhere: authentication. A static token is simple but limited. Claude.ai web, for instance, can't send a custom header. So I switched the MCP server to OAuth, which n8n exposes natively with the standard discovery endpoints. Result: any serious MCP client can connect by authenticating normally, without me having to explain anything by hand.
Step 9: making it fast and robust
This is the part I'm proudest of, because it's invisible and it took the most thought. Today, when nothing has changed, ingestion runs in two seconds instead of three to six minutes. And it's designed to avoid duplicates and losses caused by concurrent runs.
What it knows about me (and what it could know)
Today, it knows my identity, my career, my projects, my skills, my technical knowledge and how I develop. That's everything I no longer have to re-explain.
And it's meant to grow: tomorrow, my daily life, my watch, my decisions, my ideas. A memory that grows with every note.
A concrete example: a CV tailored to a job posting
Here's the most telling use case, the one that started the whole project.
The context. I come across an internship posting (Takima, "AI Software & DevOps Engineer", the PopApp project) around Green IT and Kubernetes. It asks for Java/Spring, React, Docker, Kubernetes and AI.
The request. I plug an AI into my MCP server and paste this prompt:
You are connected to my second brain via MCP (tools: second_brain_ask, second_brain_project_details, second_brain_add).
Goal: generate a CV tailored to the internship posting below, relying ONLY on my knowledge base. Don't invent anything.

Method:

1. Query my base with second_brain_ask to retrieve: my identity, background, studies, projects, skills, CV.
2. For the projects most relevant to the posting, dive into the source if you need details: second_brain_project_details, format "repo" or "repo#path".
3. Select and reorder my projects by relevance to the posting. Rewrite each item as result-oriented bullets.
4. If the posting asks for a skill my base doesn't contain, don't invent it: flag it as a gap, honestly.

Green IT section:
The posting mentions Green IT. Explicitly tie that theme to my cloud cost and resource optimisation (Terraform, budgets.tf) rather than inventing Green IT experience I don't have. Rely only on what exists in my base.

Constraints:

- Verifiable facts only: no number, date, technology or result that doesn't come from my base.
- No em dashes, no arrows.
- French, one page.
- Title, hook (objective), skills, projects, education, languages.

Before writing, list the information you found in my base and any gaps with the posting. Then propose the CV.
Translated from French, the language I actually wrote it in.
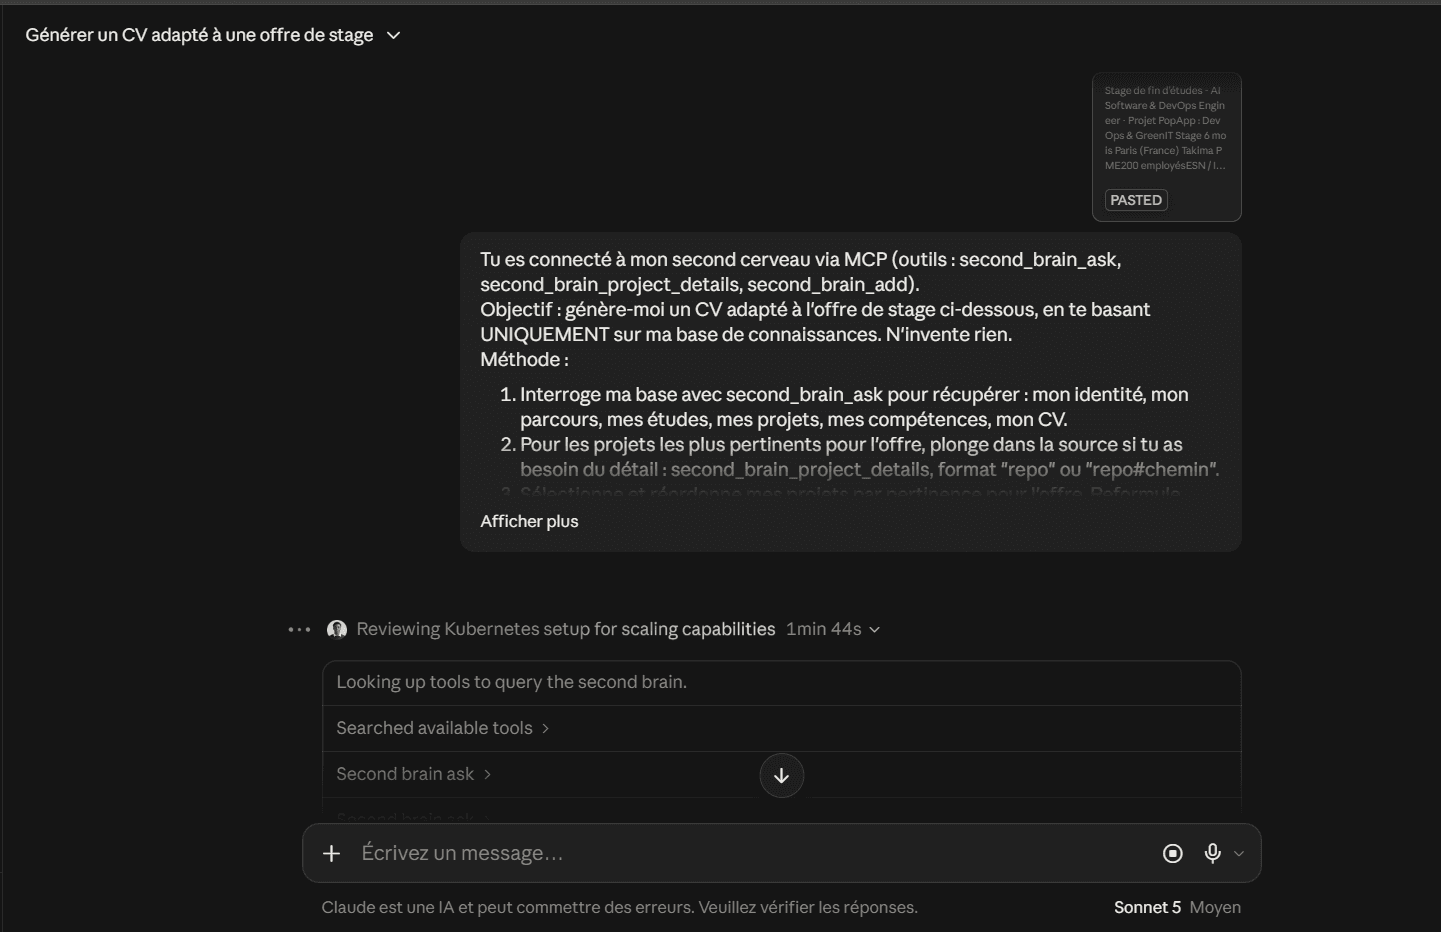
Three things matter in this prompt: the order of the tools (the base first, the source only when detail is needed), the ban on inventing (with a duty to flag gaps), and the instruction to list what was found first. That last line is what produces the screenshots below.
What happens next:
- The AI queries my base (
second_brain_ask): identity, background, projects, skills, CV. - For key projects, it dives into the source (
second_brain_project_details) to check the real details. - It selects and reorders my projects by relevance to the posting.
- It honestly flags the gaps: Kotlin, etcd, Operator Framework aren't in my base, so it doesn't invent them.
The result. A targeted CV: Kubernetes and Terraform for DevOps, Spring Boot for Java, React for the frontend, Second Brain for AI, and a section that honestly ties my experience to Green IT (cloud cost and resource control).
 1/4
The result. A targeted CV: Kubernetes and Terraform for DevOps, Spring Boot for Java, React for the frontend, Second Brain for AI, and a section that honestly ties my experience to Green IT (cloud cost and resource control).
What I found most useful wasn't the CV, though. It was the list of gaps. The AI points out the real holes in my base: projects described too quickly (React only via SIGGE, with no detail of what I did there), a project presented as a case study rather than a real mission, missing skills (Kotlin, etcd, Operator Framework). Its remark about "truncated files" deserved a check: it came less from my base than from my search engine. My indexer split notes in the middle of sentences, with no heading and no context, and only surfaced eight chunks per question. The content was often there, but badly split, so unreachable. Ever since I split one chunk per section and prefix it with its source, information I thought was missing now ranks at the top of the results, like my role on TribuneJustice. The brain is only worth what you put into it, and also what it manages to retrieve. It's a start, and it makes those holes visible.
The problems I hit (and how I solved them)
This is the part I wish I'd read when I started. Nothing went as planned.
1. The LLM provider that fell through
The problem: my first generation choice didn't work. No valid key on one side, no funds on the other. Total dead end at the generation step.
The solution: reuse a gateway I already had, OpenCode Go. But it requires a custom header, x-opencode-session, which n8n's model nodes don't expose.
The lesson: when a node won't let you do what you need, drop a level. I replaced the node with a plain direct HTTP call, with full control over the payload and headers.
2. The loop that stopped by itself
The problem: my ingestion used splitInBatches, a loop per note. It stopped early as soon as an item was empty.
The solution: drop the loop for a linear pipeline. A single flow, no fragile intermediate state.
The lesson: a loop is one more state to manage. When a linear flow works, it's simpler and more reliable.
3. Embeddings that took forever
The problem: no GPU on my VPS. Computing the vectors of 190 pieces on CPU meant about one second per piece, so three to six minutes per run. And it recomputed everything every time, even if a single note had changed.
The solution: make ingestion differential. Each piece gets a deterministic identifier, a hash of its content. Before computing, I ask Qdrant which identifiers already exist, and I only embed the new or changed ones.
The result: from three to six minutes, down to two seconds in steady state. Only the notes I just edited cost time.
4. Ghost duplicates
The problem: two concurrent ingestion runs, one scheduled and one manual, and the base contained twice the same notes.
The solution: with deterministic identifiers, an upsert overwrites instead of appending. Two simultaneous runs converge on the same index.
5. The data loss that annoyed me
The problem: while fixing duplicates, I introduced something worse. My cleanup deleted points missing from the current batch. But if a run had a stale view of the vault, it deleted the notes another run had just written. I lost four notes while testing. That kind of bug makes you doubt everything.
The solution: timestamp each point with indexed_at, and only delete an orphan if it predates the start of the run. A concurrent run, even with a stale view, does not touch notes written after it started.
The lesson: deleting what's no longer there is a destructive operation. On a concurrent system, it needs a time guard. I wrote that trap down in the project docs so I never fall into it again.
6. The silent leak of an AI note
The problem: while digging, I discovered a note written by an AI was status: active, so indexed, when it should have been quarantined. It came from an old version of the workflow.
The solution: on top of quarantine, I excluded a whole folder, the one for captures and reports, from indexing. This double protection now keeps AI notes out of the index through that path.
7. The false friend that made me doubt
The problem: a node was called "OpenRouter Model", but pointed to another gateway. A credential named "OpenAI account" had nothing to do with OpenAI. Result: hours hunting an inconsistency that was in the names.
The solution: rename things by what they do, not by a brand. And turn it into a written rule in the project.
The lesson: bad names cost more than they seem. A lying name is a bug waiting to happen.
8. "Why does an AI tell me one thing and the opposite?"
The problem: an AI told me my base was misnamed, based on a screenshot that matched nothing in my repository. A file that never existed. I checked the entire Git history, zero trace.
The solution: the golden rule, verify at the source and never trust a screenshot. That's the point of this project. An AI that makes things up is an AI without access to the truth. Here, it only has access to what's verified.
What it's useful for
The CV was the trigger, but it's only one use among others. Here's what it brings me today, and what it will bring over time.
Preparing for an interview or internship
I ask any AI: "summarize project X, my technical choices, what I learned". It answers from my notes, with exact details, not from an approximate memory.
Applications, CV, portfolio
My professional context is ready, up to date and queryable. Writing an application or a post becomes a dialogue with my own base, not a blank page.
Freelancing: answer fast and accurately
A client asks a technical question? I have the AI dive into a project's source (README, specific file) to find the exact implementation, without digging through my disk.
Daily technical memory
A lesson learned, an architecture decision, a trap hit: I capture it in the vault. The lesson of the day becomes a queryable note, not a fading memory.
One memory for all my AIs
ChatGPT, Claude, Cursor, opencode: all read and write into the same base. I no longer re-explain my context, I plug it in.
Feeding my articles and projects
What I write here is fueled by the vault. My notes, retrospectives and articles no longer start from zero: they start from what I lived.
Applying my conventions to a new project
The AI knows how I develop: structure, naming, patterns, best practices. On a new project, it applies what I've already done well elsewhere, instead of producing generic code.
Beyond work, it's also a memory for life: my projects, my goals, my admin. An AI that knows me, and knows me with my permission, because it's my base, on my server.
What this project taught me
- Failure is inevitable: designing for failure (retry, idempotence, graceful degradation) beats hoping nothing breaks.
- Data first: a destructive operation always needs a guardrail. Here, a timestamp. Otherwise, it will bite.
- Naming is designing: a badly named component is a bug waiting for its moment.
- An AI doesn't need to memorize everything: it should be able to read when needed, and only write with my consent.
- Verify at the source: that's what separates a useful AI from one that confidently makes things up.
What's next
The foundation is solid, but nothing is frozen. Coming up: a chat interface (Telegram or WhatsApp) to query the brain without opening an MCP client, automatic capture (watch, ideas) so the base feeds itself, and ever more life notes. Because deep down, this isn't an AI project. It's a memory I'm building, piece by piece.
If you're building a similar project, start simple, put guardrails in before you get hurt, and document every trap. The problems I listed here, you'll hit too. Might as well let them serve you.